Machine learning has become an important technology for analyzing complex information, identifying trends, and supporting data-driven business decisions. Predictive algorithms can deliver valuable results, but their effectiveness largely depends on the quality and structure of the information provided during training. Raw datasets may contain unnecessary attributes, inconsistent values, and relationships that are difficult for algorithms to recognize directly. Feature engineering helps overcome these challenges by converting existing information into meaningful variables that improve the learning process. It enables data scientists to extract useful characteristics, simplify complex datasets, and uncover patterns that contribute to better predictions. Individuals pursuing Data Science and AI Training in Chennai can benefit from understanding how feature engineering supports machine learning development. Learning these techniques also helps professionals build analytical solutions that meet practical business requirements.
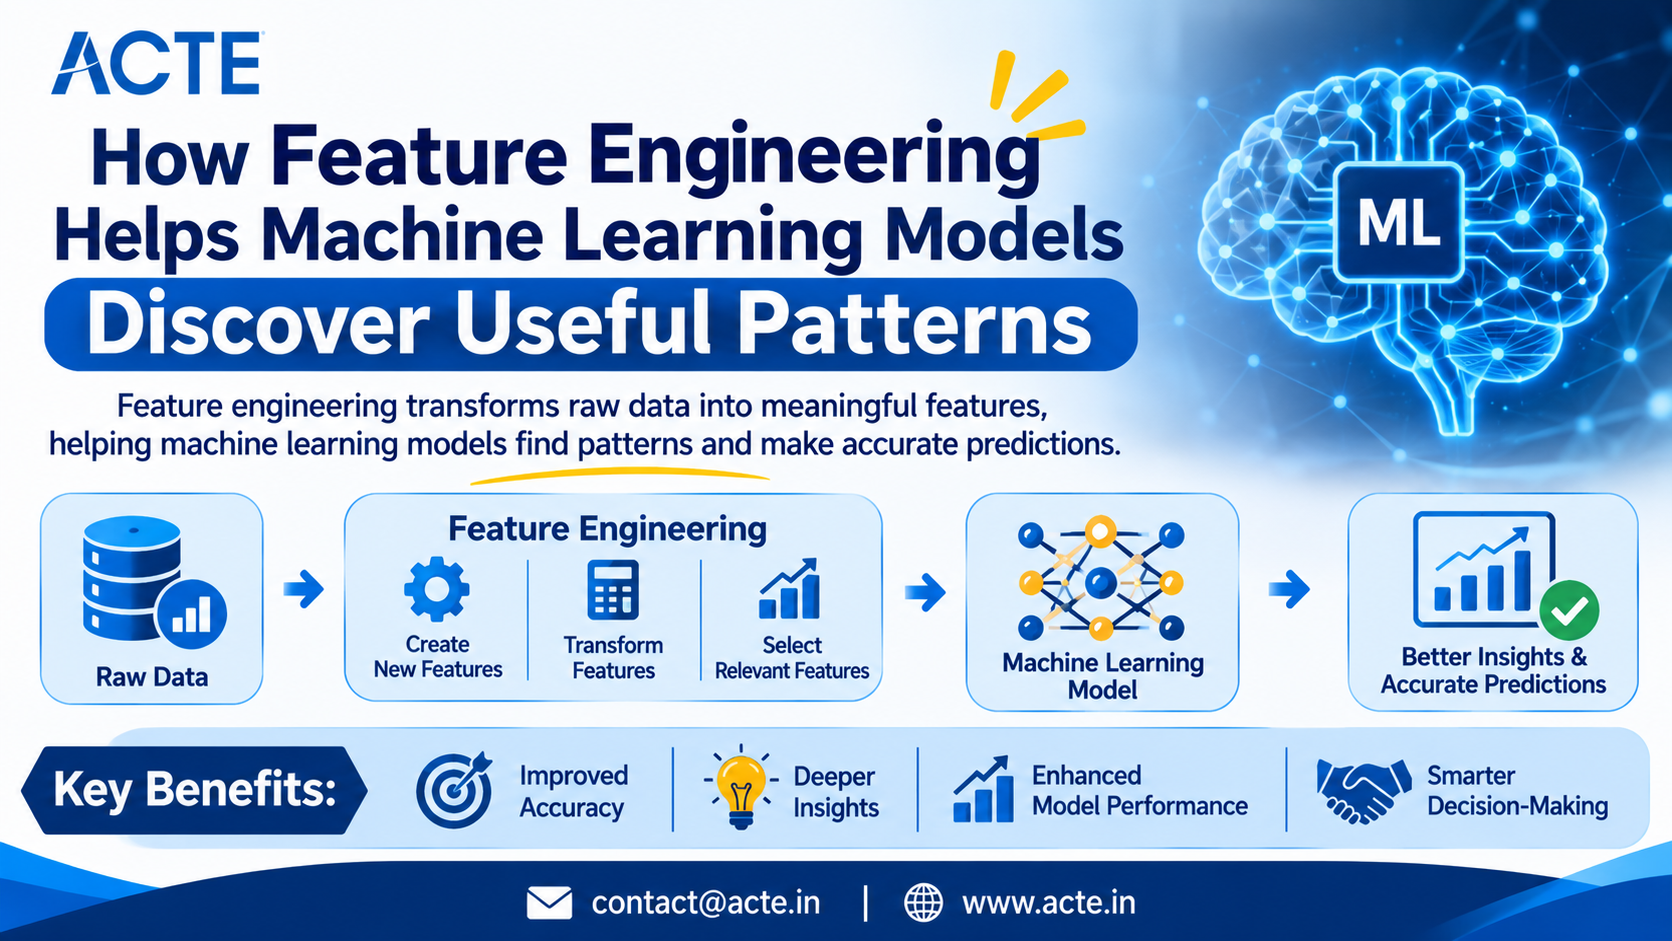
Exploring the Importance of Feature Engineering in Predictive Modeling
Feature engineering refers to the process of preparing existing variables, creating additional attributes, and selecting relevant information to improve machine learning performance. Features represent the measurable characteristics of a dataset that algorithms use to identify patterns and make predictions. Sometimes, the original information does not provide enough context for a model to understand the problem effectively. For instance, a customer database containing dates of birth can be transformed into age-related variables that provide more useful information for customer analysis. Similarly, transaction dates can be converted into weekdays, months, and seasonal indicators. These additional attributes help algorithms recognize relationships that may not be obvious in the original data. Feature engineering also allows data scientists to apply domain knowledge when preparing datasets for predictive modeling.
Transforming Unstructured and Inconsistent Data into Useful Features
Raw datasets often include missing entries, duplicate information, inconsistent formats, and numerical variables measured on different scales. These issues can influence how machine learning algorithms process information and generate predictions. Feature transformation helps organize data into representations that are more suitable for model training. Techniques such as normalization and standardization adjust numerical values, while categorical encoding converts descriptive information into numerical variables. Missing values can also be addressed using appropriate imputation techniques. For example, an online retail dataset containing product categories such as electronics, groceries, and fashion can be transformed using one-hot encoding. These preprocessing activities improve data consistency and help algorithms learn from relevant information without unnecessary complications.
Developing New Features to Identify Meaningful Relationships
Creating additional features helps data scientists reveal information that may remain hidden when examining individual variables separately. This process involves combining existing attributes, calculating derived values, and extracting relevant characteristics from available data. For example, an e-commerce company can use the total purchase amount and number of transactions to calculate average customer spending. This newly created variable can provide useful information about purchasing behaviour. Similarly, combining website visits, product views, and completed purchases can help identify customer engagement patterns. Interaction features can also reveal how multiple variables influence a prediction outcome. Learners enrolling in Data Science and AI Course in Bangalore can explore these techniques through practical exercises that demonstrate how meaningful feature creation supports more effective machine learning models.
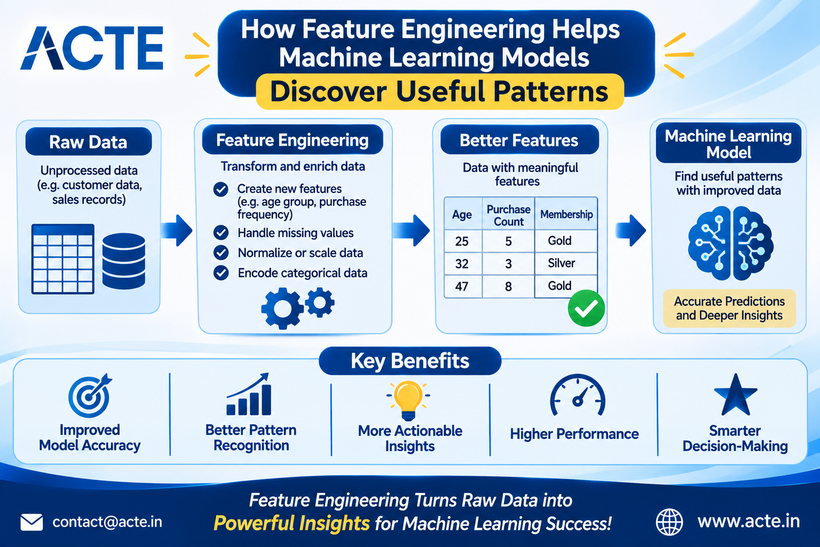
Choosing Relevant Features to Improve Model Efficiency
Using every available variable in a machine learning model does not always produce better predictions. Some attributes may provide limited information, while others may duplicate existing variables or introduce unnecessary complexity. Feature selection helps identify the most valuable inputs and remove those that contribute very little to the prediction objective. This process can simplify models, reduce processing requirements, and improve interpretability. Data scientists commonly use correlation analysis, statistical tests, recursive feature elimination, and model-based feature importance techniques. For example, customer churn prediction may depend more heavily on subscription duration, service usage, and payment behaviour than on unrelated dataset attributes. Selecting appropriate variables allows algorithms to concentrate on meaningful patterns and develop more efficient predictive models.
Understanding Feature Engineering in Real-World Industry Applications
Feature engineering supports different industries by helping organizations represent their data in ways that address specific business challenges. Banks can analyze transaction frequency, unusual spending amounts, and location changes to identify potential fraudulent activities. Retail businesses can develop features based on seasonal demand, purchasing frequency, and average order values to improve sales forecasting. Healthcare organizations can extract relevant indicators from patient records to support predictive analysis. Manufacturing companies can examine equipment operating hours, temperature fluctuations, and maintenance records to anticipate possible failures. These examples demonstrate how industry knowledge contributes to developing useful machine learning features. By understanding the objectives of different business sectors, data scientists can create variables that provide more meaningful information to predictive algorithms.
Applying Python Tools and Libraries for Feature Engineering
Python offers several libraries that make feature engineering and data preparation more efficient. Pandas helps professionals manipulate datasets, perform aggregations, and create new variables. NumPy provides numerical operations and mathematical functions for transforming information. Scikit-learn includes preprocessing techniques, categorical encoders, feature selection methods, and dimensionality reduction capabilities. These libraries allow data scientists to prepare datasets systematically and evaluate different approaches to feature creation. Common techniques include scaling, binning, date-time extraction, polynomial transformations, categorical encoding, and principal component analysis. The selection of an appropriate method depends on the dataset, machine learning algorithm, and intended prediction. Students pursuing Data Science and AI Course in Hyderabad can improve their practical knowledge by using these libraries in coding exercises and machine learning assignments.
Developing Stronger Predictive Models Through Practical Projects
Hands-on projects help aspiring data scientists understand how feature engineering influences the overall performance of machine learning applications. Instead of directly training algorithms with raw information, learners can experiment with transformations, create additional variables, evaluate feature importance, and compare model results. Projects such as customer churn analysis, house price prediction, loan eligibility assessment, sales forecasting, and recommendation systems provide valuable opportunities to practise these techniques. Comparing model performance before and after feature engineering helps candidates understand the contribution of different attributes. It is also important to apply preprocessing methods correctly to avoid data leakage between training and testing datasets. A comprehensive Data Science and AI Course can help learners strengthen these capabilities through practical assignments and industry-oriented projects.
Conclusion:
Feature engineering helps machine learning algorithms discover meaningful relationships by improving the way information is represented and processed. Techniques such as feature creation, data transformation, variable selection, and preprocessing enable data scientists to prepare more effective inputs for predictive models. These practices can improve model efficiency, simplify complex datasets, and support better prediction quality when applied appropriately. Developing expertise in feature engineering alongside Python, statistics, and machine learning provides a valuable foundation for aspiring data science professionals. Consistent practice with real-world datasets and practical projects can further improve their ability to build intelligent solutions that address industry challenges.